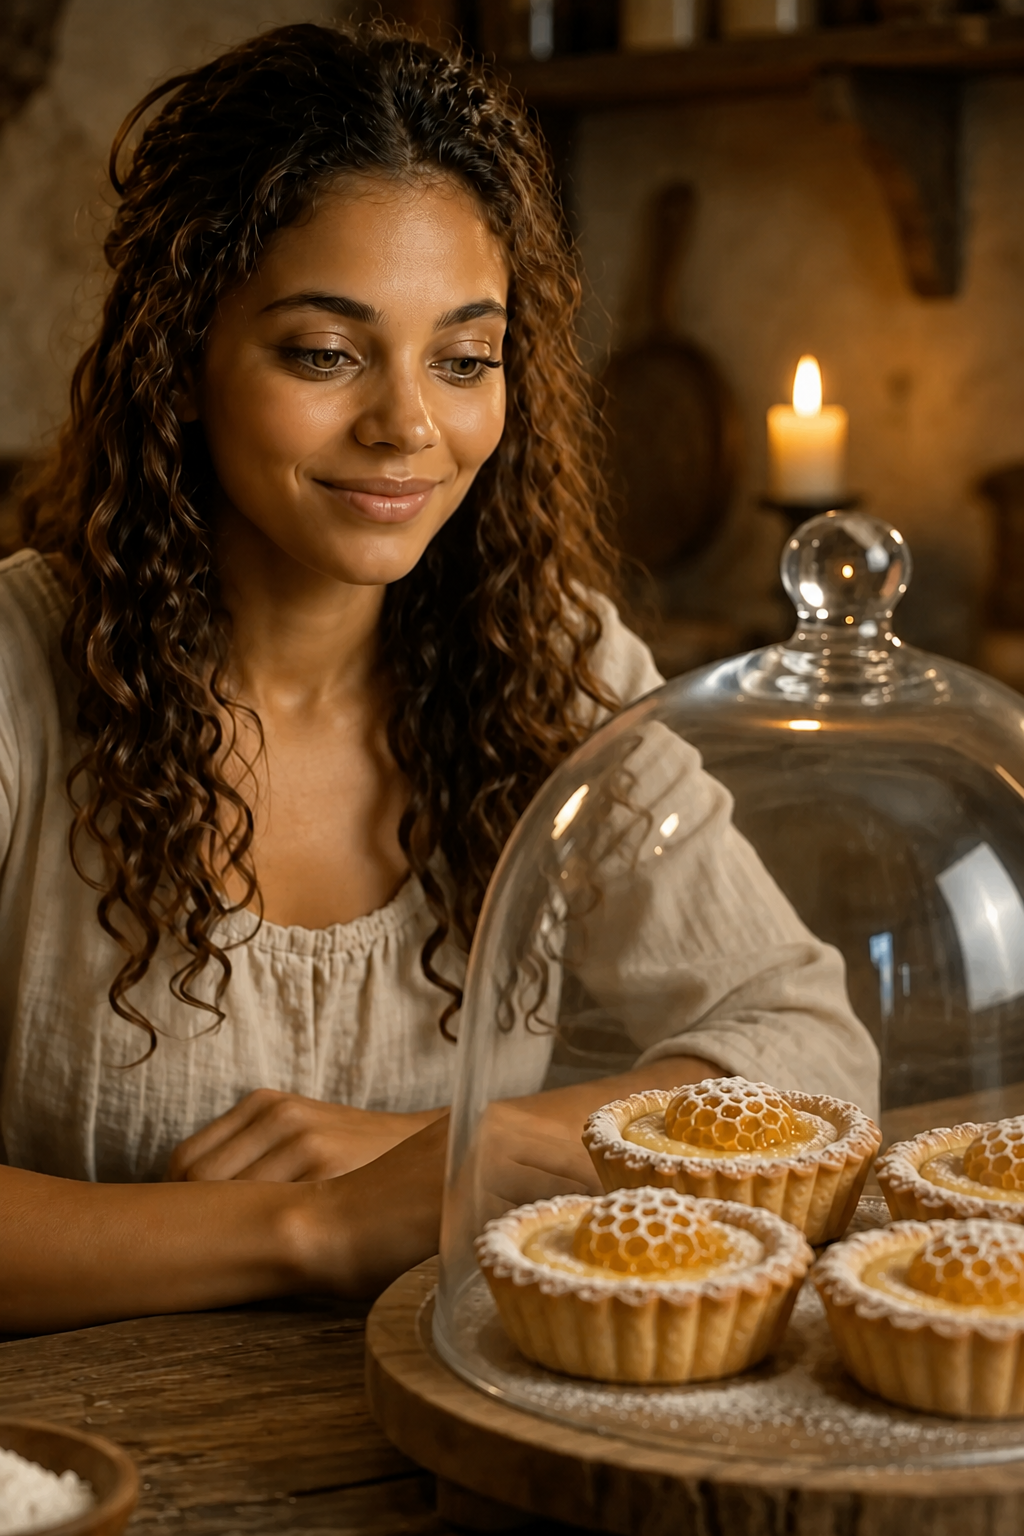
This ten-second clip came from one still image and one prompt. The character makes eye contact on cue, her expression collapses in stages instead of all at once, and on the last word of the line she cries. I don’t mean the wet-eyed anime shimmer most AI video gives you. Actual tears track down her face, timed to the dialogue.
I didn’t storyboard it. I didn’t keyframe anything. I filled in a template.
The template is called a timed relay prompt, and the name is friendlier than it sounds. Think of a relay race. Instead of describing the whole performance at once, you break it into short timed legs of about two seconds each. Each leg carries one small piece of the performance, like an expression or a glance, then hands the baton to the next. It needs no animation skills and no software, only a schedule.
It’s the biggest upgrade I’ve made to my AI character animation workflow this year. Credit where it’s due: I found it in The Neuron, which picked it up from Prompt Mastery’s tutorial Plenty of prompts get passed around creator circles, and most of them are hype. I ran this one start to finish, and I’m going to show you exactly what it produced, including the parts it got wrong.
The Problem: Every AI Character Is a Talking Head
If you’ve tried animating a character for narration content, you know the failure mode. You feed a motion model a beautiful still and a line of audio, and you get back a mannequin. The lips move, the head does a gentle idle sway, and the eyes stare at nothing. It’s technically “animated” and emotionally dead, and viewers clock it in under a second.
The instinct is to fix it with adjectives: emotional, cinematic, melancholy, expressive. That doesn’t work, because adjectives don’t tell the model when to do anything. “Melancholy woman looks at pastries” gives the model a mood and no schedule. With nothing to sequence, it defaults to the idle sway.
The relay prompt fixes this by doing the director’s job for the model.
The Template
Here it is ready to steal:
Scene: [describe the room, character, camera angle, and mood]

Audio line: [paste the dialogue]

Goal: Make the character feel physically present, not like a generic talking head.

Write a timestamped action plan:

0-2s: facial expression and posture

2-4s: hand movement or eye contact

4-6s: body movement

6-8s: final gesture or reaction
Keep the movements subtle, realistic, and synced to the emotional beats of the line.
What the Relay Looked Like Filled In
My test scene: a young woman in a candlelit rustic kitchen, leaning low over a table where two honeycomb custard tarts sit under a glass cloche. The audio line: “You made these for me? I haven’t seen anything this beautiful since… before.”
Gemini’s timestamped plan mapped the emotional arc onto the clock. It opened with a softening gaze and sinking shoulders. On “for me?” her eyes lift to meet an unseen person while a hesitant finger traces the glass dome. Through the middle of the line, a weight shift and a controlled breath. On the final word, “before,” a single tear, a bowed head, and a held frame.
One sentence in the plan is worth more than the whole template, and I want to tattoo it on every motion prompt I write from now on:
“Her movements are reactions, not presentations.”
A talking head presents. It performs at the camera. A character reacts: something is happening inside her, and the movement leaks out. The timestamp blocks force you (and the model) to choreograph reactions instead of stacking adjectives.
The Scorecard: What Actually Rendered
I ran the plan through Google Vids, then went through the output frame by frame against the plan.
Landed: the opening expression and posture. She starts exactly in the source pose, low on her forearms and absorbed in the tarts, and the expression reads inhabited from frame one. There’s no idle-sway mannequin phase.
Landed: the eye contact, on sync. Right on the tail of “for me?”, her eyes lift from the tarts and find the camera, and they stay there. This is the moment that sells the whole clip, and it hit within half a second of where the plan scheduled it.
Landed: the micro-movement through the middle. Gaze back down, a slight head tilt, small shifts through “I haven’t seen anything this beautiful.” It’s softer than the forearm-to-forearm weight transfer the plan called for, but her body stays alive between beats.
Overdelivered: the tear. The plan asked for a single tear on “before.” The model gave her tears in both eyes, welling on cue and tracking down her cheeks into the final held frame. It went one notch past the spec, and it played.
Fumbled: the finger tracing the glass. The plan’s most specific physical instruction, a slow, reverent circle traced on the dome’s exterior, never happens. Her hands stay tucked under her lean for the whole clip.
Landed: the held ending. After the last word, the clip holds her bowed, eyes-closed pose for a full second before cutting, exactly as the plan asked.
Call it four and a half out of six. The misses aren’t random, either, and the pattern is worth knowing before you write your next prompt.
The Lesson: Faces Are Reliable, Hands Are Not
Motion models right now are very good at faces, gaze direction, and gross posture, and unreliable at discrete prop interactions, like a finger touching a specific object at a specific time, especially when the hand has to travel into position. My clip shows it cleanly: every facial and postural beat rendered, and the one hand-meets-object beat evaporated.
The practical rule: front-load your emotional beats into face, eyes, and posture. Treat hand-and-prop gestures as a bonus, never as a load-bearing beat. If your scene’s emotional payoff depends on the character picking up the locket, you’re going to have a bad time. If the payoff lives in her eyes and the locket is set dressing, you’ll get your shot.
Adapting the Timestamps To Your Audio
The template assumes an eight-second line. Real dialogue doesn’t cooperate.
The blocks are proportions, not law. My delivered line ran about nine seconds, and the output clip came out at ten. The model stretched the plan to fit and kept the order intact. For a longer narration beat, rescale the blocks (0-3s, 3-6s, 6-10s) and keep the same arc: establish, connect, shift, land.
One more production note: my output came back 1080×1920 vertical, which is native size for Shorts, Reels, and Pinterest video. If your discovery strategy leans on vertical platforms, this workflow drops straight into it.
Tool Notes (and a confession about Hailuo)
The relay prompt works with any tool. It’s a structured action plan, so you can paste it into Hailuo, Runway, Kling, Pika, or whatever ships next month. Since this is a review, here’s how the tools scored too.
I bought a pile of Hailuo credits in a Christmas sale, and after months of burning through them I can give you a consistent number: roughly 70 percent of what I generate is unusable. The part that took me too long to accept is that it doesn’t matter who writes the prompt. Me, ChatGPT, Gemini, Claude: the hit rate barely moves. The bottleneck isn’t prompt quality. It’s the model’s execution lottery. Hailuo still earns its keep in my pipeline for camera movement and environmental motion, where it’s strong. For character performance (expression changes, timed eye contact, emotional escalation), this Google Vids output beat my Hailuo results on the first attempt.
What sold me on Vids is that it’s simple the way the rest of the Workspace apps are simple, not “simple for an AI tool.” It isn’t perfect, though. The project cap is currently 30 minutes (recently tripled from 10). That sounds limiting for long-form storytelling, but long-form narration has natural act breaks anyway. Plan one around the half-hour mark and you’ve got a Part One/Part Two structure.
The other catch is branding. Vids stamps AI-generated clips with Google’s watermark, and every output also carries SynthID, an invisible marker embedded in the file itself. I add my own channel branding to everything I publish regardless, but don’t treat the AI mark as something to hide. Platforms increasingly require disclosure of realistic synthetic content (YouTube has a checkbox for exactly this), and SynthID means the file is identifiable as AI no matter what sits on top of it.
Brand your work, tick the disclosure toggle, and you’re clean with both Google’s terms and YouTube’s policy, while some of your competitors are running clips through sketchy watermark-removal sites and hoping nobody checks.
A cautionary note on tool choice, because it’s timely: I’d been considering Higgsfield for this test, and I’m glad I read the fine print first. Their July terms update granted the company a perpetual, irrevocable, transferable license to everything users uploaded and generated. That included training rights that survived account deletion and extended to faces uploaded for character creation.
The viral outrage framed it as “Higgsfield owns your content,” which wasn’t technically true. They never claimed ownership. They claimed a license so broad the distinction stopped mattering. After the backlash they walked most of it back. The revised terms (effective late August) restore a service-only license, keep private content private, and confirm your commercial rights, though training on your content by default reportedly still stands for non-enterprise accounts.
Higgsfield may be fine for you now. The bigger point is that for those of us generating original characters and IP, the terms of service are part of the tool. Read the license section before you upload the face of a character you plan to build a story universe around, because the license clause is what binds you, whatever the headlines say.
(A comedy note from the original Gemini chat: when I asked Gemini to just make the video, it told me flatly, “No. I cannot generate or render video files.” I mentioned I had a Google Vids subscription. Next message: “Your video is ready!” Never let anyone tell you the machines are always right.)
For the advanced crowd running a full pipeline, my flow is still image generation, then color grade, then motion pass. The relay prompt slots between grade and motion as the script the motion pass follows. If you want more on the camera side, the Ultimate AI Camera Movement Guide (affiliate link) is the reference I use for movement vocabulary.
Why AI Character Animation Finally Feels Directable
Every trick I’d tried before for AI character animation was about describing harder: more adjectives, more mood, more cinematography jargon. The timed relay prompt is the first one that’s about directing. You tell the performer what to do, in order, on a clock, motivated by the line. That’s what direction is, and the models respond to it.
Steal the template and fill it with your own character and your own line. When you write the plan, keep one sentence taped above your desk: reactions, not presentations.
Pin this for later: